
Our model for the way clinicians speak.
1st of 12for finished text and medical terms
Sentences from the 44ai-clinical-de test set, exactly as Klara wrote them.
Off-the-shelf speech models aren't built for clinical work.
In the GP practice, on the ward and in the emergency department, people speak medicine, often in dialect. And when they dictate, they say the punctuation and line breaks out loud. General-purpose speech recognition is built for everyday language.
GP practice
Consultation notes, dictated between two patients
Ward
The progress note, dictated on the ward round
Emergency department
The initial assessment, once the patient is stable

That's why we built Klara ourselves.
One model for clinical speech.
Hear for yourself.
Press play. Both systems were given the same clip from the test set. Here is what each one wrote, with the red pen marking what a clinician would still have to correct before signing off.
0:00
 Corti SymphonyCorti
 Scribe v2 MedicalElevenLabs
 gpt-4o-transcribeOpenAI
 Dragon Medical OneMicrosoft
- Scribe v2ElevenLabs
 Nemotron 3.5 TranscribeNVIDIA
- MAI-Transcribe-2Microsoft
 Cohere TranscribeCohere
 stt-async-v5Soniox
- Whisper large-v3OpenAI
 Nova-3Deepgram
Klara 44ai
misheardheard correctly, but not formatted as in the report
Four examples from the test set. Full results in the paper and on GitHub.
Less red ink.
We ran twelve speech recognition systems on three clinical dictation test sets and compared every transcript with the finished report.
The next-best system still leaves 20 corrections for every 100 words and punctuation marks. Klara leaves fewer than half as many.
9per 100
Klara44ai
20per 100
Corti SymphonyCorti
23per 100
Scribe v2 MedicalElevenLabs
25per 100
gpt-4o-transcribeOpenAI
28per 100
Dragon Medical OneMicrosoft
28per 100
Scribe v2ElevenLabs
30per 100
Nemotron 3.5 TranscribeNVIDIA
34per 100
MAI-Transcribe-2Microsoft
44per 100
Cohere TranscribeCohere
46per 100
stt-async-v5Soniox
47per 100
Whisper large-v3OpenAI
57per 100
Nova-3Deepgram
Formatted accuracy, %. The system's output compared with the finished report, including punctuation and formatting.
- Klara44ai
- Corti SymphonyCorti
- Scribe v2 MedicalElevenLabs
- gpt-4o-transcribeOpenAI
- Dragon Medical OneMicrosoft
- Scribe v2ElevenLabs
- Nemotron 3.5 TranscribeNVIDIA
- MAI-Transcribe-2Microsoft
- Cohere TranscribeCohere
- stt-async-v5Soniox
- Whisper large-v3OpenAI
- Nova-3Deepgram
Medical term accuracy, %. Medications, diagnoses, procedures and anatomy, written correctly.
- Klara44ai
- Corti SymphonyCorti
- Scribe v2 MedicalElevenLabs
- gpt-4o-transcribeOpenAI
- Scribe v2ElevenLabs
- MAI-Transcribe-2Microsoft
- stt-async-v5Soniox
- Nemotron 3.5 TranscribeNVIDIA
- Whisper large-v3OpenAI
- Cohere TranscribeCohere
- Dragon Medical OneMicrosoft
- Nova-3Deepgram
Word accuracy, %. Recognised words only, without formatting.
- Klara44ai
- gpt-4o-transcribeOpenAI
- Scribe v2 MedicalElevenLabs
- MAI-Transcribe-2Microsoft
- Scribe v2ElevenLabs
- Corti SymphonyCorti
- stt-async-v5Soniox
- Nemotron 3.5 TranscribeNVIDIA
- Cohere TranscribeCohere
- Whisper large-v3OpenAI
- Dragon Medical OneMicrosoft
- Nova-3Deepgram
Word accuracy on dialect speakers, %. Word accuracy for Swiss, German and Austrian dialect speakers.
- Klara44ai
- gpt-4o-transcribeOpenAI
- Scribe v2 MedicalElevenLabs
- MAI-Transcribe-2Microsoft
- Scribe v2ElevenLabs
- Corti SymphonyCorti
- stt-async-v5Soniox
- Nemotron 3.5 TranscribeNVIDIA
- Cohere TranscribeCohere
- Whisper large-v3OpenAI
- Dragon Medical OneMicrosoft
- Nova-3Deepgram
Everyone is good at textbook German.
On the ward, nobody speaks textbook German. Speech is mumbled, in dialect and unstructured.
Klara 90.7gpt-4o-transcribe 81.7Scribe v2 Medical 81.3MAI-Transcribe-2 80.3Scribe v2 80.0Corti Symphony 77.0Soniox 74.9Cohere 70.5Nemotron 69.8Whisper 69.3Dragon Medical One 54.1Deepgram 51.7Standard GermanNon-native speakersNon-nativeGerman and Austrian dialectsDialectsSwiss dialectsDialectsCheck it for yourself.
The scoring code, the normalisation rules and every transcript from all twelve systems are public.
$ git clone https://github.com/44ai-labs/44ai-klara-evaluation
$ cd 44ai-klara-evaluation
$ make install
$ make score

## All three test sets, weighted by audio duration

| System                       | Formatted | Word | Medical |
|                              |           |      |   terms |
| ---------------------------- | --------- | ---- | ------- |
| Klara                        |      90.9 | 93.9 |    90.4 |
| Corti Symphony               |      80.1 | 89.9 |    89.6 |
| ElevenLabs Scribe v2 Medical |      76.7 | 90.7 |    89.0 |
| gpt-4o-transcribe            |      74.9 | 90.9 |    88.5 |
| Dragon Medical One\*         |      72.2 | 80.4 |    76.7 |
| ElevenLabs Scribe v2         |      72.1 | 90.0 |    87.8 |
| Nemotron 3.5 Transcribe      |      69.6 | 87.3 |    81.5 |
| MAI-Transcribe-2             |      66.0 | 90.6 |    84.6 |
| Cohere Transcribe\*†         |      55.8 | 82.5 |    78.1 |
| Soniox stt-async-v5†         |      53.8 | 88.0 |    83.6 |
| Whisper large-v3\*†          |      53.3 | 82.1 |    78.3 |
| Deepgram Nova-3†             |      42.6 | 80.0 |    73.3 |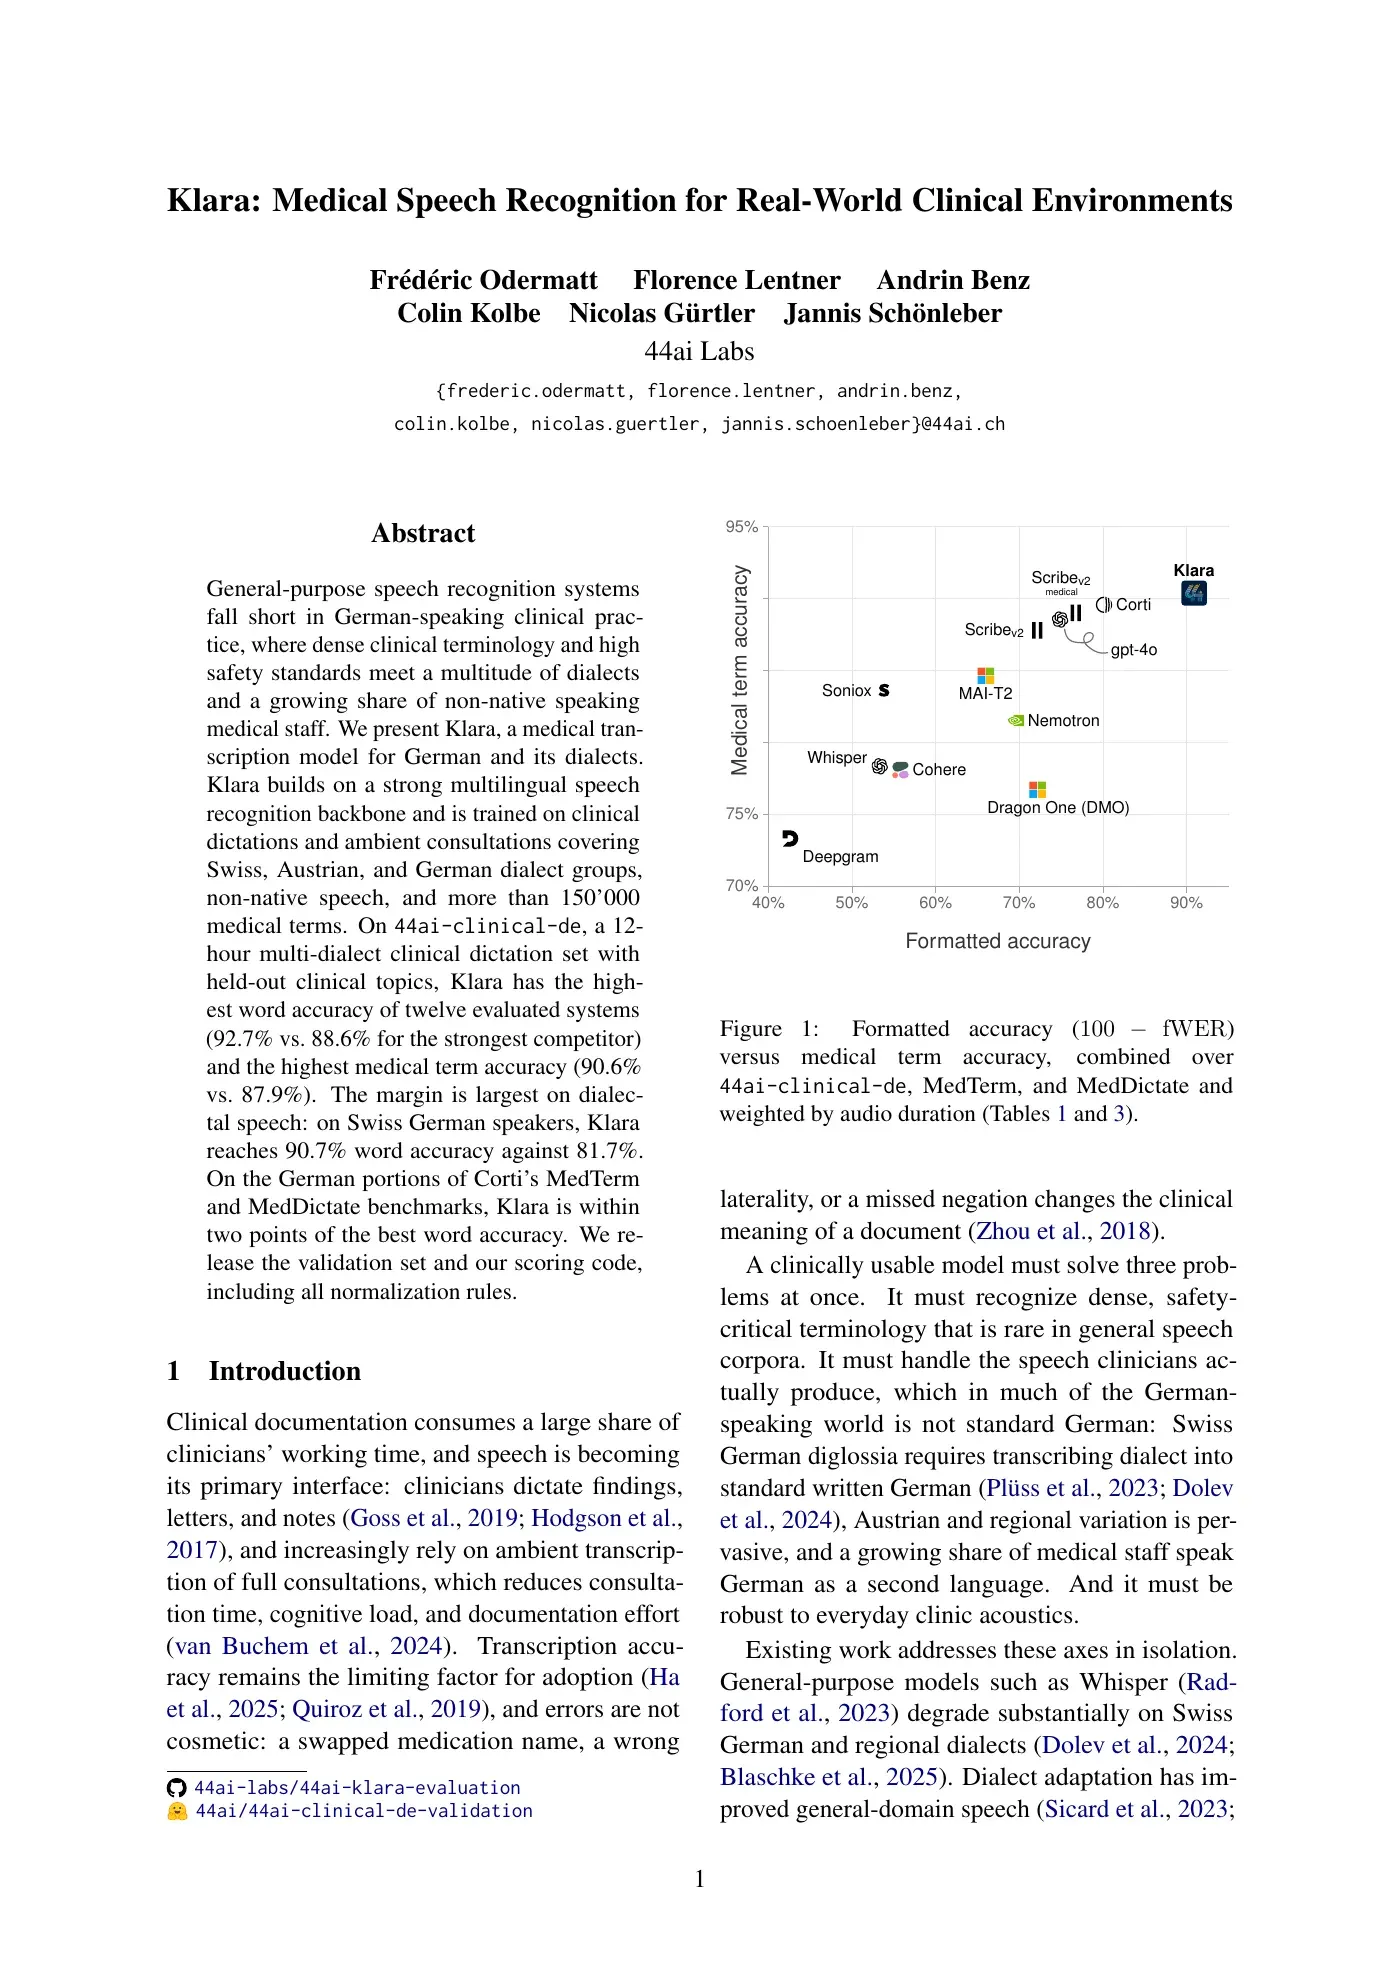
Top quality, full data sovereignty.
You decide where Klara runs: on your own servers or in a sovereign cloud. Both with the same quality.
- On premises, in your own data centre
- Sovereign cloud
- Medical device
- ISO 13485:2016
- EU AI Act
- EU GDPR
- No US CLOUD Act
- ISO/IEC 27001Hosting provider
- BSI C5Hosting provider
Want Haidy® at your institution too?
Klara is the speech recognition inside Haidy®. We'll show you how it works with your reports and your workflows.
- ReportsHaidy® Reporter
- DictationHaidy® Dictate
- WorkflowsHaidy® Hive